
In this guide
How it works
Open a PDF with readable text and select the pages you need.
Run the HTML export and download the resulting file.
Open it in a browser and check reading order, special characters and paragraphs.
Input, result and limits
| Property | Details |
|---|---|
| Input | |
| Output | HTML |
| Important limitation | Text output without reconstructing pictures, tables or page layout. |
The workflow in six views
1Input
Open a PDF with readable text and select the pages you need.
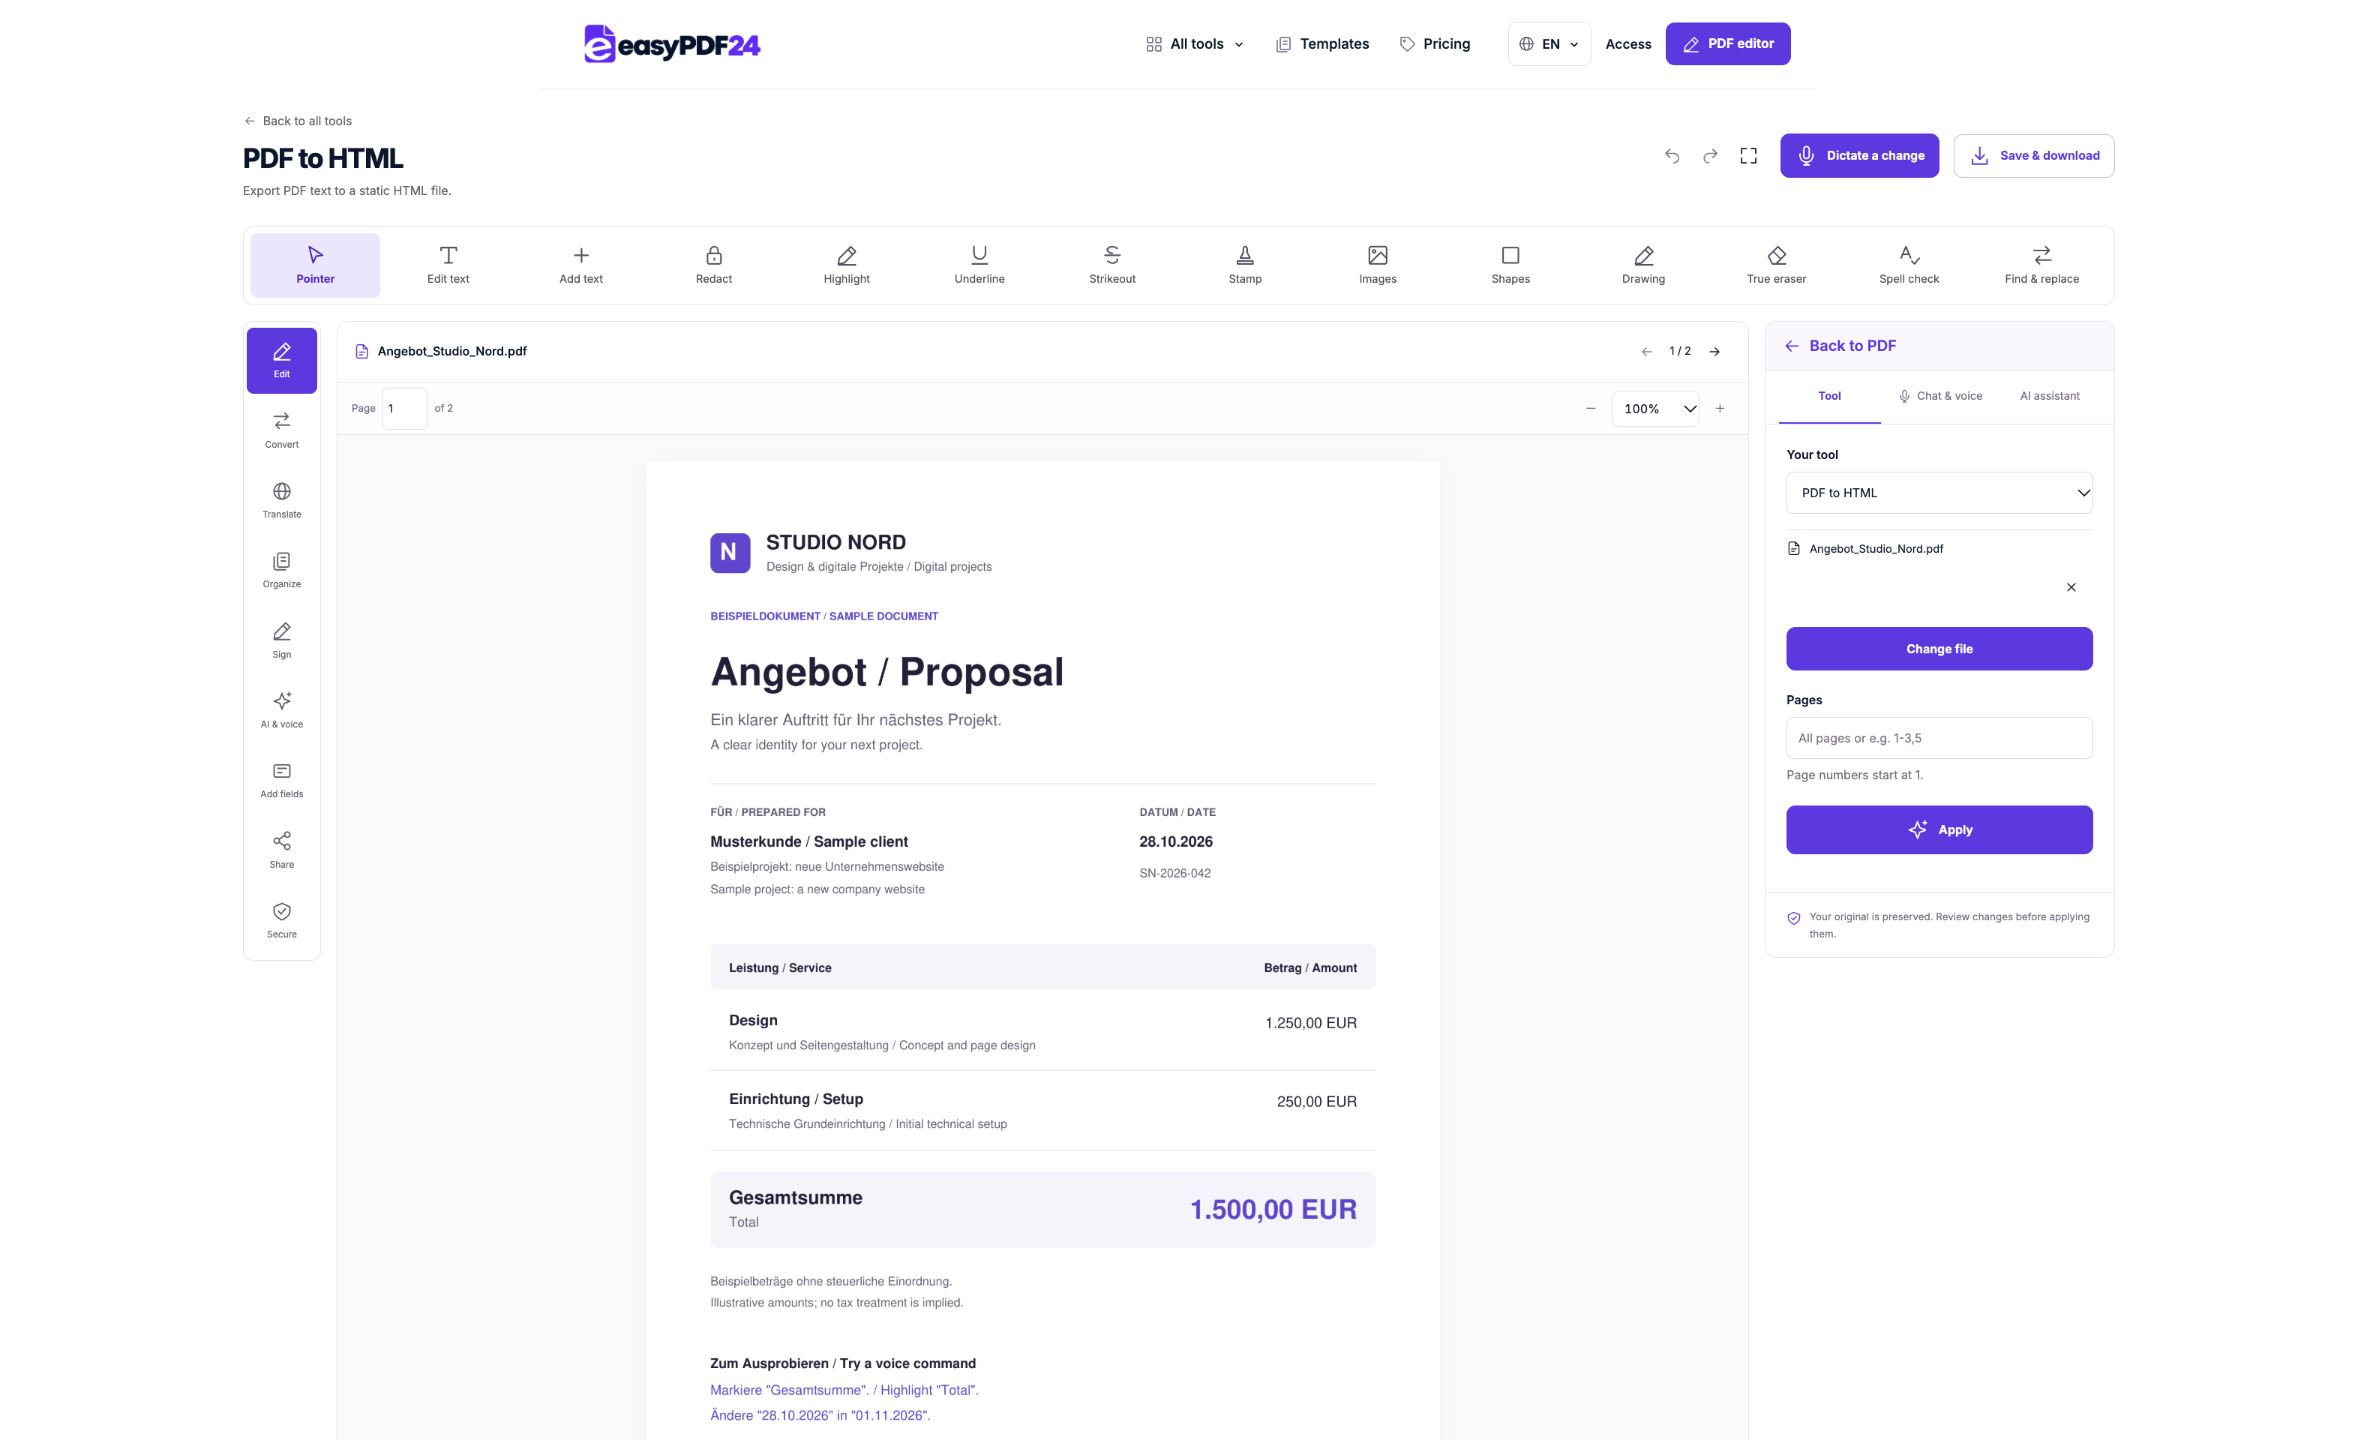
2Settings
Run the HTML export and download the resulting file.
3Apply
PDF → HTML
4Before and after
Visual page → Extracted text
5Review
Compare names, figures and special characters Check reading order and paragraphs Reopen the downloaded file
6Save
Open it in a browser and check reading order, special characters and paragraphs.
Example
Before
Visual page
After
Extracted text
Check these details in the result
- Compare names, figures and special characters
- Check reading order and paragraphs
- Reopen the downloaded file
A text foundation for further work
For example, you can prepare wording from a digital PDF manual for a simple browser page. Page headings help you check each passage against its source. Multiple columns and tables may appear in a different extracted order from the visual PDF. Edit those passages into a sensible reading sequence before publishing or reusing them.
The original design is not reproduced
The result contains text rather than reconstructed pictures, table grids or interactive forms. Embedded programs from the document are not carried across. A page consisting solely of a scanned image needs text recognition first. If the visual appearance matters more than reusable wording, exporting the PDF page as an image may be a more suitable next step.
Frequently asked questions
Will pictures and columns be preserved?
This is a text-oriented HTML export. It does not reconstruct images or the original column layout.
Is the HTML automatically published online?
No. You receive a downloadable file and choose how and where to use it afterward.