
In this guide
How it works
Open a PDF containing selectable text. For a scanned document, run OCR first.
Choose PDF to Word and start the export.
Open the DOCX file in Word or a compatible application. Check reading order, paragraphs and special characters.
Input, result and limits
| Property | Details |
|---|---|
| Input | |
| Output | DOCX |
| Important limitation | Text output without reconstructing pictures, tables or page layout. |
The workflow in six views
1Input
Open a PDF containing selectable text. For a scanned document, run OCR first.
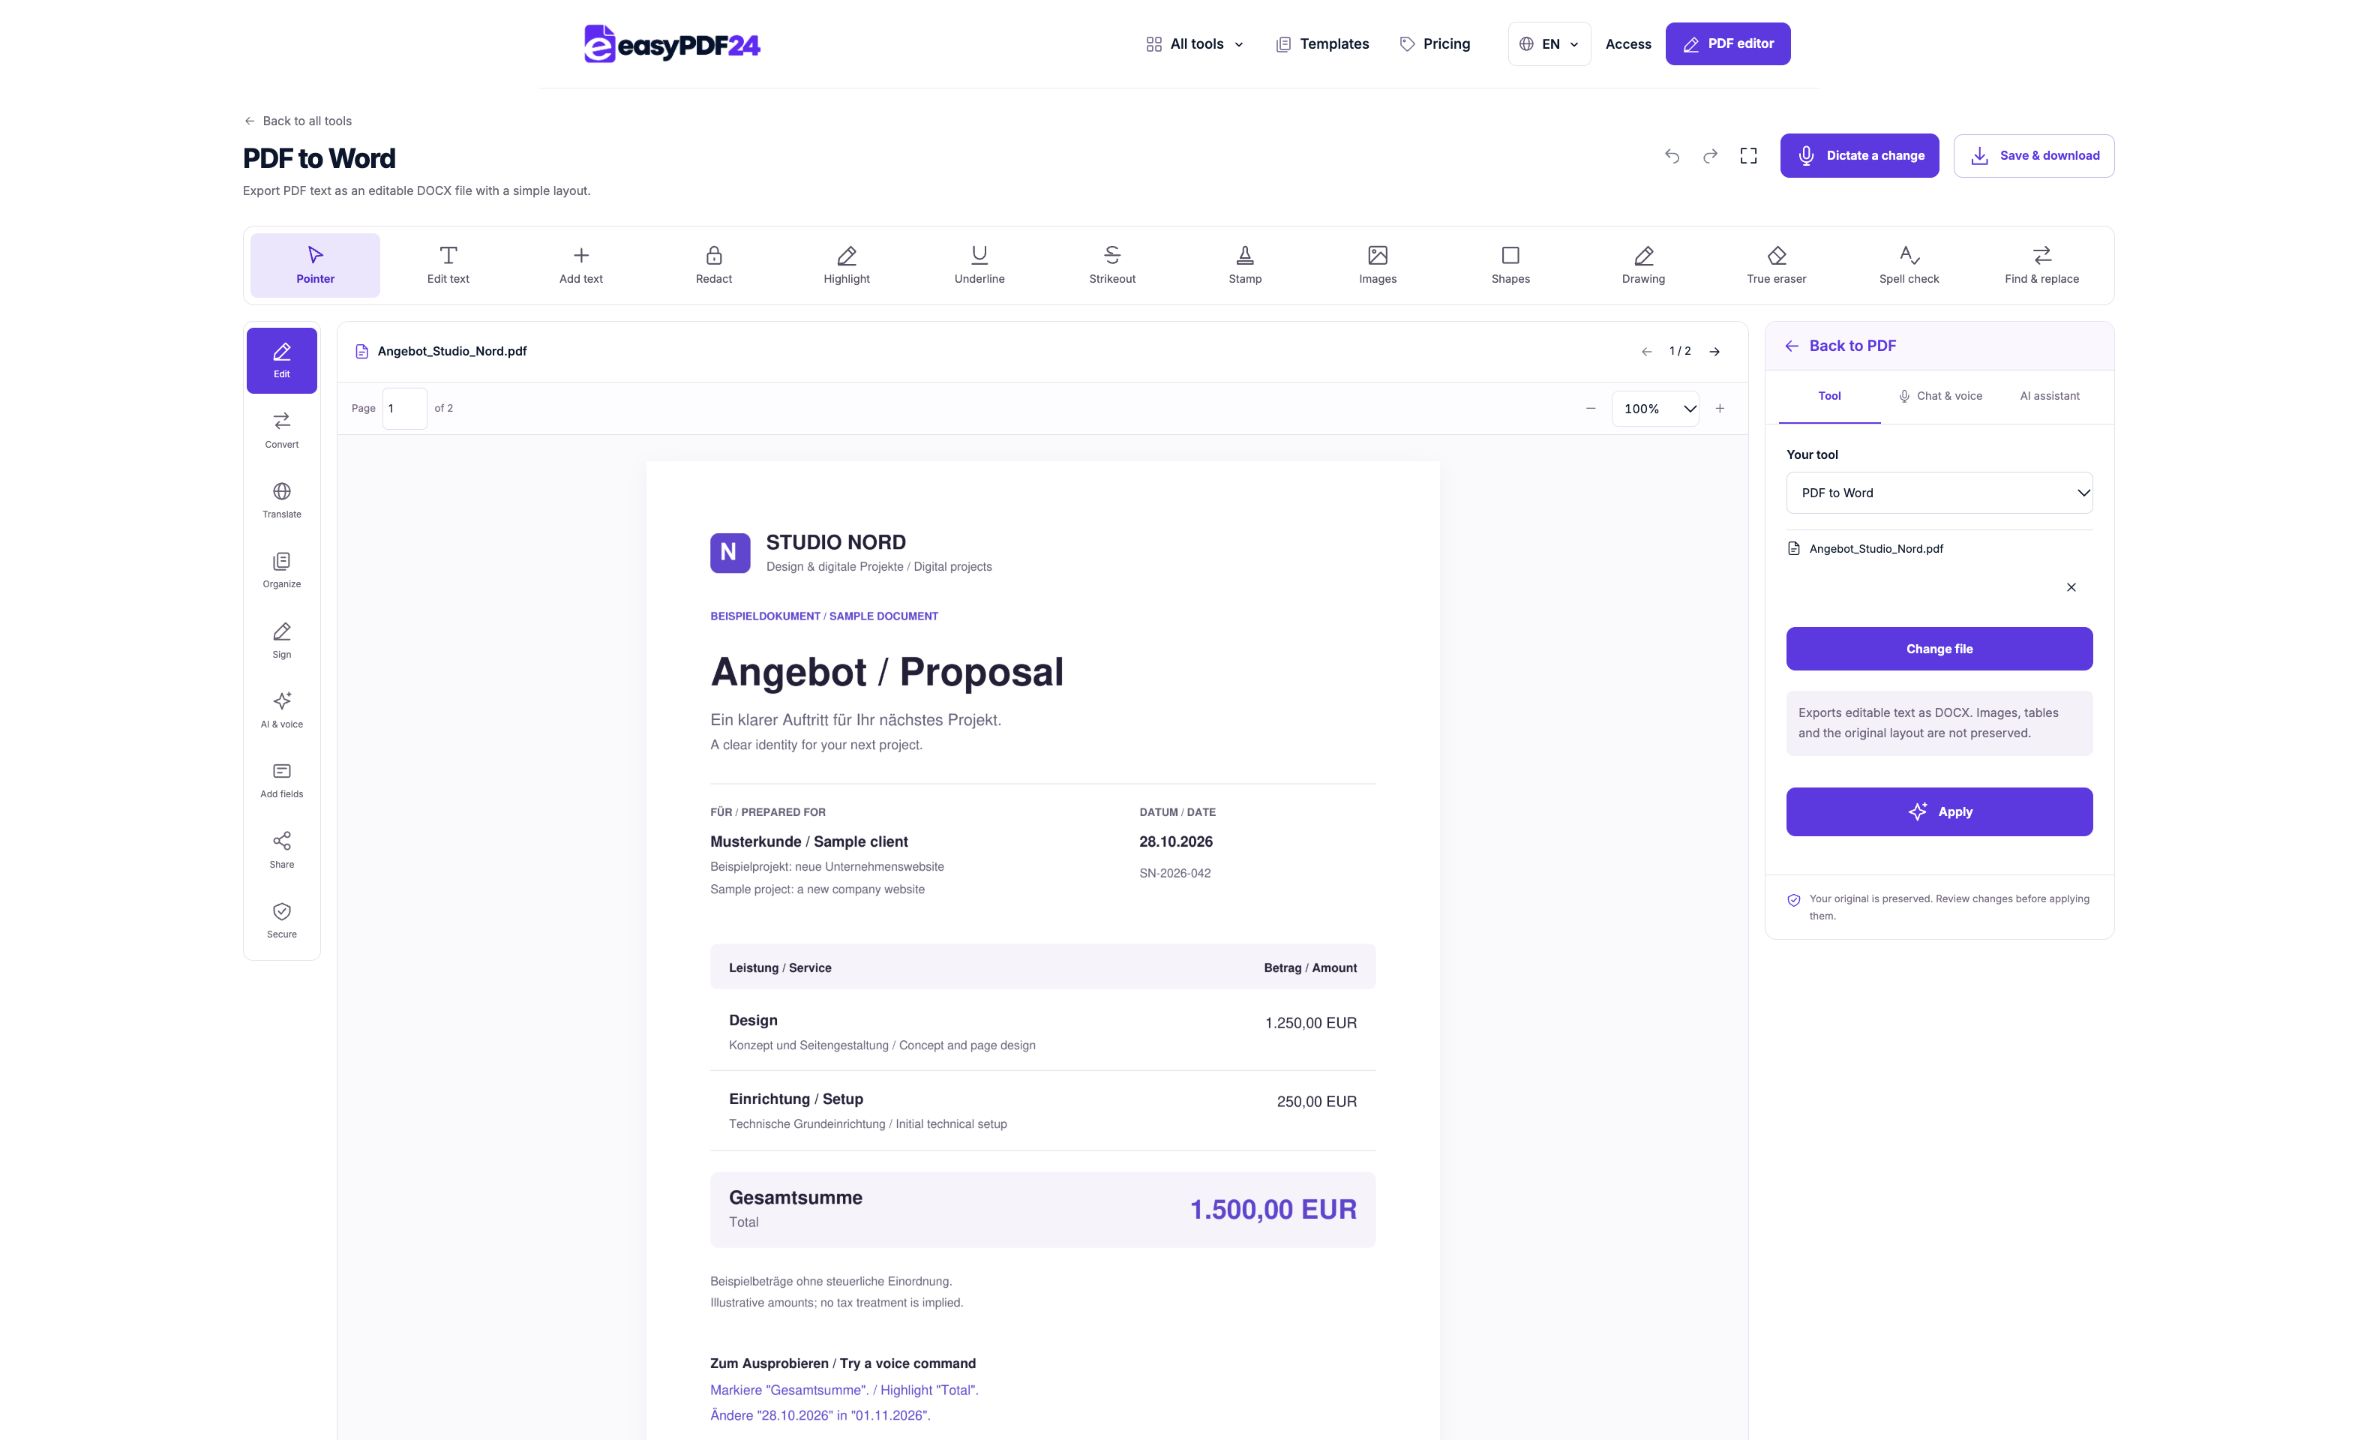
2Settings
Choose PDF to Word and start the export.

3Apply
PDF → DOCX
4Before and after
Visual page → Editable content
5Review
Compare names, figures and special characters Check reading order and paragraphs Test editing the objects you need
6Save
Open the DOCX file in Word or a compatible application. Check reading order, paragraphs and special characters.
Example
Before
Visual page
After
Editable content
Check these details in the result
- Compare names, figures and special characters
- Check reading order and paragraphs
- Test editing the objects you need
Choose a text export when rewriting is the real task
Converting a PDF to Word is useful when you need to work with its wording in a document editor. You might want to reorganize notes, rewrite a long explanation or reuse a passage in a new document. easyPDF24 exports existing selectable PDF text into a basic DOCX file. This gives you editable text to work with, but it is not a promise to reproduce the original page design. Make that distinction before deciding whether conversion is the right next step.
If you only need to change one date, a short name or a single sentence in its existing location, direct PDF editing can be a shorter route. Conversion followed by rebuilding and exporting a new PDF introduces more opportunities for layout differences. If you need to rewrite several paragraphs, change headings or reorganize sections, working in Word or another compatible document editor is often more appropriate. When the original editable source exists, use it if possible. A fresh copy of that source will usually preserve more of the author's structure than text recovered from a finished PDF.
Check that the PDF contains usable text
Open the PDF and try selecting and copying a sentence. A successful selection suggests that the document has a text layer, but inspect the pasted result as well. Some files display correct-looking text while storing unusual character mappings or a reading order that differs from the visual layout. A short copy-and-paste check can reveal missing letters, unexpected spaces or words appearing in the wrong sequence before you convert the whole document.
A scanned page may contain only an image of text. In that case, the export cannot recover ordinary text just by changing the file extension. Supported OCR can add a recognized text layer to German or English printed scans. Run OCR first when appropriate, then check the recognized wording against the visible page. Names, figures, dates and special characters deserve particular attention. OCR is a recognition step with possible errors, not a guarantee that the source has become an accurately structured Word document. If the scan is blurred, tilted or partly obscured, improving the source image may be more useful than repeatedly converting the same uncertain text.
Understand what the DOCX output includes
The current export takes text extracted from the PDF and places it in a straightforward Word document. It does not carry over the original images, recreate tables as editable Word tables or preserve the full page layout. Text lines become simple paragraphs, and page boundaries from the source are represented by page breaks. This structure is a starting point for editing the wording, rather than a finished reconstruction of a designed brochure, form or presentation.
That behavior can be helpful when your aim is to reuse the text without inheriting a complex layout. It also means you should allow time for cleanup. A paragraph that occupied several lines in the PDF may arrive as several separate paragraphs in the DOCX. A table may arrive as text whose relationships need to be rebuilt manually. Before exporting a large document, consider how much structure you actually need. If the result must match a highly designed original precisely, locate the source document or use a workflow suited to that reconstruction instead of expecting this text-oriented export to supply it automatically.
Run the conversion and inspect a representative page
Open the intended PDF in PDF to Word and start the export. Keep the original available while you review the DOCX. Open the downloaded file in Word or a compatible application and inspect a representative section before editing extensively. Choose a section with a heading, ordinary text and any layout feature that is important to your task. Compare the wording with the PDF rather than checking only whether the DOCX opens successfully.
Start with the beginning and end of the document, then look at sections with columns, tables or special characters. This gives you an early sense of the cleanup required. If the text is mostly correct but paragraph boundaries are awkward, you can repair structure in the word processor. If entire sections are missing because they were images, return to the PDF and assess whether supported OCR is suitable. If characters are badly encoded, a different source or export may be necessary. Identifying the problem early prevents you from polishing the first page of a document whose remaining content has not been recovered reliably.
Rebuild paragraphs and headings deliberately
After confirming the wording, organize the text into useful paragraphs. PDF lines reflect where text happened to fit on a fixed page; they are not always meaningful paragraph boundaries. Join lines that belong to the same paragraph and remove breaks that interrupt a sentence. Check hyphenated words at line endings carefully. A hyphen may be part of the word, or it may have been inserted only because the word crossed a line boundary in the source layout.
Apply heading styles in the word processor when the document needs a clear hierarchy. A visually large line in the PDF is not automatically exported as a structured Word heading. Decide which lines are titles, section headings, captions or ordinary body text. Consistent styles make later editing easier and help maintain a coherent appearance when text is added or removed. Do this after reviewing the extracted wording, so that formatting does not distract you from missing or incorrect content. Keep the PDF open as a reference while you rebuild the structure, but allow the new document to flow naturally instead of forcing every line to end exactly where it did in the source.
Treat columns, tables and footnotes as separate checks
Multi-column pages can produce an extraction order that differs from the order a person follows visually. A sentence from the right column may appear between lines from the left, or a sidebar may be mixed into the main text. Compare the first and last sentences of each column and read the converted section continuously. If the narrative jumps unexpectedly, inspect the source page and move the relevant text into the correct sequence before making further editorial changes.
Tables require a different kind of review. The DOCX export does not recreate an editable table with the original cells and borders. Check which labels belong to which values and rebuild the table manually if you need that structure. Pay particular attention to decimal values, units and headings that apply to several columns. Footnotes, captions and repeated headers may also appear among the extracted lines. Keep them only where they serve the new document's purpose, and verify references after moving them. A text export can recover useful wording while still requiring you to reconstruct the relationships that the original page communicated through its layout.
Verify names, numbers and recognized characters
Do not limit proofreading to ordinary spelling. Check personal and organization names, reference codes, dates, amounts and units against the PDF. A single mistaken character can change a reference or value even when the surrounding paragraph reads smoothly. This is especially important after OCR, where similar-looking characters such as letters and digits may be confused. Compare the visible source rather than assuming that a spellchecker can validate specialized terms or numerical information.
Search the Word document for a few distinctive phrases from different parts of the PDF. This can help reveal missing sections, but it does not replace a systematic check of important content. If the PDF contains mathematical notation, unusual symbols or a specialized alphabet, inspect those passages directly. A basic text export may not preserve their intended representation. Mark uncertain passages for review instead of silently guessing what the author meant. When you edit the wording after conversion, keep a clear distinction between correcting extraction errors and making intentional content changes, so that you can explain which differences came from the export and which were your own revisions.
Use a practical example to plan the cleanup
Suppose you have a six-page workshop handout and want to turn its instructions into a revised training document. The handout contains ordinary text, a two-column checklist and several illustrations. Export the selectable text, then compare the recovered instructions with the PDF. Join line-based paragraphs where necessary and apply a consistent heading structure. Rebuild the checklist as a table or list in the word processor, based on the relationships shown in the original page.
The illustrations are not included by this text export, so decide whether the new document needs them. Obtain suitable source graphics or prepare an appropriate image workflow rather than assuming they will appear later in the conversion. If you use a rendered PDF page as an image, remember that it is a picture of the page rather than an editable reconstruction of its individual objects. Once the text and graphics are assembled, review the new document as its own publication. It should communicate the updated instructions clearly, not merely resemble the old page at a glance while containing broken paragraphs or mismatched checklist values.
Handle difficult results without repeatedly converting blindly
If the DOCX is empty or contains little text, check whether the PDF is image-based. If it contains jumbled text, examine reading order and unusual character encoding. If the wording is correct but the layout looks different, remember that this tool intentionally produces a basic text document. These are different situations and need different responses. Repeating the same export without changing the source or the workflow is unlikely to repair the underlying issue.
For a supported scan, run OCR on the relevant pages and verify its result before exporting again. For a complex layout, decide whether manual cleanup is reasonable or whether finding the original source would save time. For a small correction, return to direct PDF editing instead of reconstructing a whole document unnecessarily. Keep a working copy of the DOCX while you experiment with formatting, and retain the original PDF as a reference. If the receiving task requires an exact visual match, test that requirement early. A successful text recovery and an exact page reproduction are different outcomes, and this export is designed around the first.
Finish the Word document before making a new PDF
Once you have corrected the text and rebuilt the necessary structure, review the document in the word processor. Check headings, paragraph spacing, tables, page breaks and any newly added graphics. Remove repeated headers or line breaks that no longer make sense in the new layout. Read the document continuously to catch transitions that were disrupted by the original fixed-page extraction. Save the editable DOCX as the new working source if you plan to maintain it later.
If you need to share the finished result as a PDF, export it from the word processor or use Office to PDF for a supported file, then inspect that new PDF separately. Fonts and pagination can differ between conversion environments. A complete conversion workflow ends with accurate, usable text and a checked output in the format your recipient actually needs.
Frequently asked questions
Will the Word file look exactly like the PDF?
No. This export creates text with simple formatting. Complex tables, image positioning and exact page breaks require separate work.
Can I turn the DOCX file back into a PDF?
Yes. Use the PDF export in your word processor or the easyPDF24 Office to PDF tool.
Why does one paragraph become several paragraphs in Word?
The export follows text lines extracted from the fixed PDF page. A line ending in that source is not always a real paragraph boundary, so the basic DOCX can contain several short paragraphs where you expected one flowing passage. Compare the wording with the PDF and join lines that belong together. Check line-ending hyphens before removing them, because some are part of the word rather than a layout artifact. Apply heading and paragraph styles after repairing the structure.
Will the conversion recover the original Word source file?
No. It creates a new DOCX from the available PDF text. It does not recover the original authoring file, its editing history or its complete layout structure. If that source is available, use it for substantial revisions. The export is useful when the PDF is your available reference and editable wording is the main requirement.